
Goal
Estimate storage for an embedding index from vector count, dimensions, and precision.
Worldwide context
Saved once here, used across the site.
Currency changes display only. Country selection guides tax input; no tax rate is guessed.
Estimate storage for an embedding index from vector count, dimensions, and precision.
Bytes = vectors × (dims × bytesPer + metaKB × 1024).A clearer path to an answer
This page keeps the calculation transparent: define the goal, enter the matching values, inspect the method, and decide what the result means in your situation.
Estimate storage for an embedding index from vector count, dimensions, and precision.
Vector count · Dimensions · Precision · Metadata per vector
Bytes = vectors × (dims × bytesPer + metaKB × 1024).
Calculate, review the assumptions below, then compare a related tool when the decision needs more context.
Estimate storage for an embedding index from vector count, dimensions, and precision.
Open the Vector Database Size Estimator pageMore technology tools
Download PDFDownload Word (.doc)
Enter your values above and choose Calculate to see the result here.
Calculation map
Bytes = vectors × (dims × bytesPer + metaKB × 1024).
Bounded, transparent calculation
Your recent runs stay in this browser session only.
Formula: Bytes = vectors × (dims × bytesPer + metaKB × 1024).
Raw vector bytes plus per-item metadata give the working set before index overhead. ANN indexes (HNSW, IVF) add their own overhead on top.
Worked example: 7.17 GB total.
The displayed limits are checked before the handler runs. Model-specific domain checks may also reject impossible or non-finite inputs.
Methodology: This calculator follows the WorldCalculate input, formula, precision, and boundary policy. Read the official methodology.
Calculator usage statistics
This section counts anonymous successful Calculate submissions, not unique visitors. Counts and top tools appear only when trusted aggregate data is available; country analysis is shown only under the same condition and reporting threshold.
Answer-first guide
Estimate storage for an embedding index from vector count, dimensions, and precision. Start with one clearly defined goal, enter values in the units shown, and keep the result attached to the assumptions below.
This tool is useful when your question includes vector database size, embedding storage, FAISS memory. It returns the outputs declared in the calculator contract rather than a live quote, approval, diagnosis, or professional sign-off.
Vector count · Dimensions · Precision · Metadata per vector. Keep the same time period, unit system, and currency wherever the form requires comparable values.
Run the worked example first, compare its output with the page's example, then change one input at a time. This makes an unexpected result easier to trace to a unit, boundary, or assumption.
Need a wider view? Browse Technology Calculators or compare the related tools below. The WorldCalculate methodology explains how formulas, examples, limits, and revisions are reviewed.
Bytes = vectors × (dims × bytesPer + metaKB × 1024).
Raw vector bytes plus per-item metadata give the working set before index overhead. ANN indexes (HNSW, IVF) add their own overhead on top.
7.17 GB total.
Context and background
Computing tools distinguish number bases, decimal and binary storage, network prefixes, transfer units, and visual ratios before performing the arithmetic.
Technical systems use several measurement conventions because software, hardware, networks, and design each describe quantities differently. Explicit representation prevents a familiar abbreviation from hiding a different definition.
Research and review
Researched by Hassan ALRowaie, Founder and editorial researcher at WorldCalculate.
This guide follows the live calculator's declared inputs, formula, worked example, assumptions, validation boundaries, and source-backed methodology. The review date describes editorial review of the calculator explanation; it is not a promise that external facts or rates remain current.
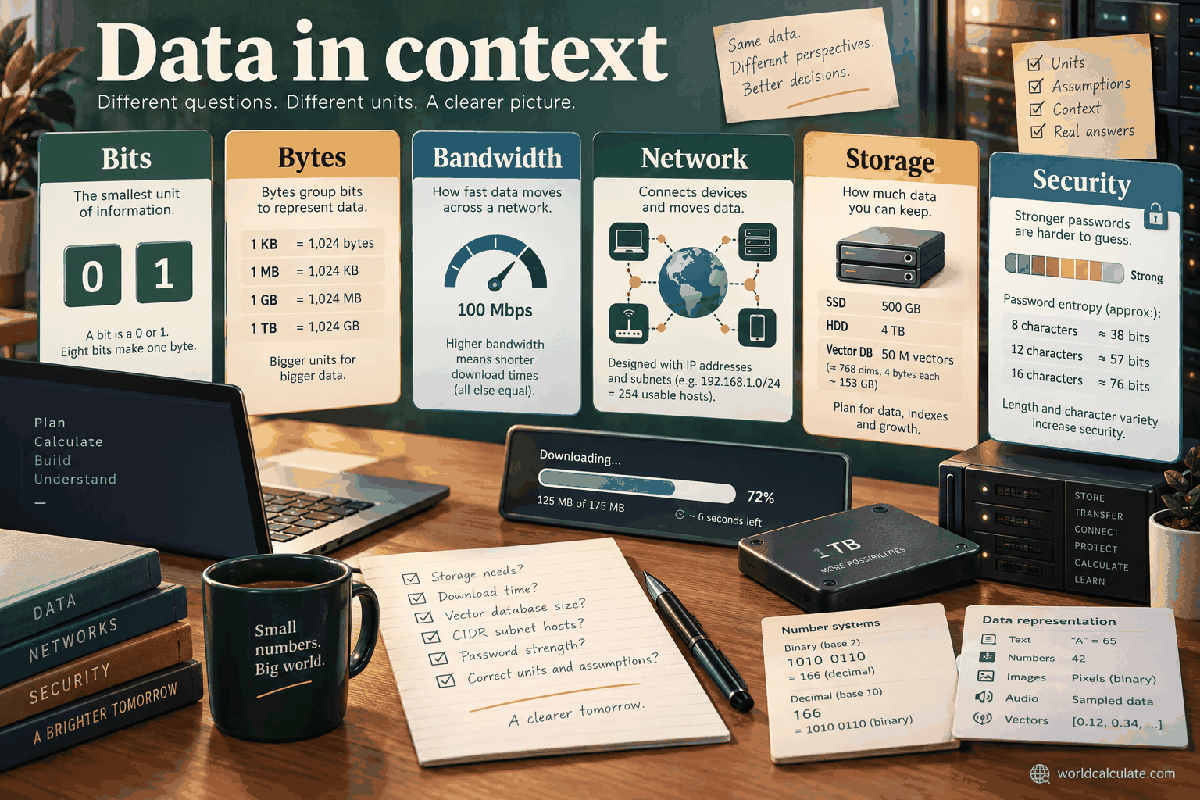
A vector database estimate is most useful when it separates the bytes that describe an embedding from the bytes that describe the item around it. This calculator starts with a count of vectors, a fixed number of dimensions, and a selected number of bytes for each stored component. It then adds a flat average for metadata and reports the resulting byte total in decimal gigabytes. That is a deliberately narrow baseline: it represents one logical flat copy of the vector and its per-vector payload. It does not quietly invent an approximate-nearest-neighbor index size, a replica count, a compression ratio, or a disk-reservation policy. Use it to establish a reproducible raw-storage baseline, compare precision choices, test metadata assumptions, and see how quickly a collection grows. For a production capacity decision, carry the inputs forward into measurements for the chosen index, service, hardware, replication policy, backup policy, and workload. The arithmetic is simple, but the assumptions around each term determine whether the number is a useful planning figure or a misleading promise.
An embedding is a numerical representation of an item such as a document passage, image, product description, audio segment, or user profile. The representation is usually a fixed-length vector: an ordered collection of numeric components produced by an embedding model or another feature-generation process. Similarity search compares these vectors according to a chosen distance or similarity rule, but the calculator does not evaluate similarity and does not know what the components mean individually. It only needs to know how many components are stored for each vector and how many bytes are allocated to each component.
The Vector count field describes how many vector records are being stored. It can mean one vector per document, one vector per chunk, one vector per image, or several vectors per source item. That modeling choice matters. If one document is split into ten chunks and every chunk gets its own vector, the vector count is roughly ten times the document count before considering failed, duplicate, or retired records. A source catalog with one vector per item and a search corpus with multiple vectors per item are different workloads even when both are described informally as a collection of documents.
A vector is not the same thing as the original content. The embedding usually supports retrieval or classification, while the original text, image, permissions, timestamps, and other fields may be stored in a separate payload. The metadata allowance is the place in this estimate for a flat average of those associated bytes when they are considered part of the same per-vector working set. If content is held in another system, the vector estimate remains useful, but it should not be mistaken for the complete storage requirement of the application.
Dimension count and vector count are independent. A collection can have many short vectors or fewer long vectors, and total vector bytes depend on both. The dimensions do not indicate quality, relevance, or a universal accuracy level. A higher-dimensional embedding can require more storage without automatically producing a better search result, while a lower-dimensional representation can be appropriate for a particular model and task. Choose dimensions from the actual embedding output or planned model configuration rather than increasing the value merely to obtain a larger estimate.
The Dimensions field is the number of stored components in each vector. In this record it accepts whole numbers from 1 through 1,000,000. If an embedding model returns 1,536 values per item, enter 1,536. If a preprocessing step concatenates two vectors, the stored dimension may be the sum of their lengths, provided that the resulting object is actually stored as one vector. If a system stores those representations separately, count them as separate vector payloads or use a dimension and count description that matches the physical layout.
For a fixed precision and fixed metadata allowance, doubling dimensions doubles only the vector portion of the estimate. It does not double a fixed metadata portion. This distinction becomes important when metadata is large. With 1,536 dimensions at four bytes each, the vector portion is 6,144 bytes per record. With 768 dimensions at the same precision, it is 3,072 bytes. If each record also has 1 KB under this calculator's conversion rule, the totals per record are 7,168 and 4,096 bytes respectively, so the metadata share changes as the vector length changes.
The collection scale is linear in the number of records. Ten million vectors with the same dimensions, precision, and metadata average use ten times the baseline bytes for one million vectors. This linearity makes the calculator useful for early growth tables, but it does not mean that every operational subsystem scales with exactly the same slope. Index graphs, postings, caches, tombstones, replicas, and compaction space can have their own coefficients or temporary peaks. Use the linear result as the common raw-data denominator before adding those measured terms.
Vector count can also change because of re-embedding. A new model or chunking policy may create a new vector for every source item before the old collection is removed. During that transition, a deployment can temporarily hold both generations, plus an index build workspace. The calculator can estimate each generation separately and can estimate their sum as a simple raw baseline, but it does not infer migration overlap from a single vector count. Include the transition window explicitly in a capacity plan.
The Precision selector is expressed in bytes per stored component, not bits per component. The available choices are float32 at 4 bytes, float16 at 2 bytes, and int8 at 1 byte. For a vector with 1,536 dimensions, those choices require 6,144, 3,072, or 1,536 bytes for the vector values before metadata is added. The selector values are exact menu values, so a free-form label or an unsupported numeric choice is not a valid way to describe another representation.
Four-byte float32 values provide the largest raw component allowance among the listed options. Two-byte float16 values use half as many raw vector bytes at the same dimension. One-byte int8 values use one quarter as many raw vector bytes as float32. These are storage relationships, not quality rankings. Changing precision can affect similarity calculations, recall, numerical range, model compatibility, and the need for auxiliary scale information. A smaller estimate is not evidence that the compressed or lower-precision representation will behave equivalently for a real search task.
The calculator treats bytesPer as an average direct allocation for every component. It does not add per-vector scales, zero points, block headers, alignment padding, lookup tables, or conversion buffers. That simplification is intentional because the selector is designed for quick scenarios rather than for parsing a particular binary format. If an actual representation has a documented block size and auxiliary data, use its measured or documented encoded size for a final decision and keep this result as a lower-level comparison baseline.
Precision should be compared while holding the other inputs constant. For example, changing only float32 to float16 shows the direct value-storage reduction without confusing it with a change in vector count or payload schema. If the production system stores both a full-precision copy and a search copy, calculate both copies separately and add them. A selector describing the search copy does not account for an archival or re-ranking copy unless that extra storage is included in metadata or in an external planning calculation.
Metadata per vector is a flat average entered in KB. It can represent an identifier, tenant or collection key, timestamps, labels, filterable attributes, permission markers, source references, or another payload that is stored alongside the vector. The field accepts zero through 1,000,000 and allows fractional values. A value of 1.5 therefore describes an average of one and a half KB under the calculator's conversion rule; it does not claim that every record has a physically identical payload.
The formula defines each entered KB as 1,024 bytes by multiplying metaKB by 1024. This is a specific contract for the field, even though everyday storage terminology sometimes uses KB for 1,000 bytes. Do not silently substitute 1,000 when reproducing this calculator. A metadata value of 1 KB contributes 1,024 bytes per vector, a value of 0.5 contributes 512 bytes, and a value of 0 contributes no metadata term. The final output uses a separate decimal GB convention, so the presence of 1024 in the metadata conversion does not make the reported GB binary.
Averages are useful when payload sizes vary. Suppose half the records carry 512 bytes of metadata and half carry 1,536 bytes under the same byte convention. Their average is 1,024 bytes, so 1 KB is a reasonable input for a first estimate. If a small number of records contain very large text or arrays, an arithmetic mean may hide a costly tail. Measure total payload bytes divided by vector count, then compare that average with a percentile or worst-case planning figure before choosing a capacity reserve.
Be explicit about where metadata physically lives. If identifiers and filter fields are copied into the vector service, include them in metaKb. If the service stores only a compact key and retrieves the full record from another store, include only the co-located bytes in this estimate and plan the external store separately. If metadata is duplicated for filtering and for display, both copies belong in the relevant storage plan. The calculator cannot detect double counting or missing payload fields from the number alone.
The calculator uses the stated formula: Bytes = vectors x (dims x bytesPer + metaKB x 1024). The expression inside the parentheses is the estimated bytes for one vector record. The first product, dims x bytesPer, counts the numeric vector components. The second product, metaKB x 1024, converts the entered metadata allowance into bytes. Adding the two terms keeps the vector payload and the associated flat metadata visible before the per-vector result is multiplied by the number of records.
The units make the derivation auditable. Dims is a count of components, and bytesPer is bytes per component, so their product is bytes per vector. MetaKB is a number of KB per vector, and the fixed 1,024 factor converts that term to bytes per vector under this field's rule. Adding two byte quantities is valid. Multiplying by vectors, which is a count of records, produces total bytes. There is no index multiplier, replica multiplier, or hidden percentage in this expression.
The displayed GB value is total bytes divided by 1,000,000,000. Because the output convention is decimal GB, a total of 7,168,000,000 bytes is 7.168 GB. The calculator also reports the estimated amount per 1,000 vectors in MB by taking the bytes per vector, multiplying by 1,000, and dividing by 1,000,000. That secondary result is a convenient density measure; it follows the same byte assumptions and does not add separate operational overhead.
A good hand check calculates the per-vector value first. With one million vectors, 1,536 dimensions, 4 bytes per component, and 1 KB of metadata, the vector term is 1,536 x 4 = 6,144 bytes, the metadata term is 1 x 1,024 = 1,024 bytes, and the combined per-vector value is 7,168 bytes. Multiplying by 1,000,000 produces 7,168,000,000 bytes. Dividing by 1,000,000,000 gives 7.168 decimal GB before display rounding.
The default inputs are 1,000,000 vectors, 1,536 dimensions, float32 precision at 4 bytes, and 1 KB of metadata per vector. Begin with the vector values: 1,536 dimensions multiplied by 4 bytes equals 6,144 bytes per vector. Next convert metadata: 1 KB multiplied by 1,024 equals 1,024 bytes per vector. The flat record baseline is therefore 6,144 + 1,024 = 7,168 bytes for every vector under the stated average.
The total follows by multiplying 7,168 bytes by 1,000,000 vectors. The result is 7,168,000,000 bytes. Dividing by 1,000,000,000 gives 7.168 decimal GB. The result display rounds the index working set to two decimal places, so the example is shown as 7.17 GB. The unrounded numeric value remains the useful value for an independent calculation, a comparison table, or a threshold decision near a boundary.
The secondary density result is 7.168 MB per 1,000 vectors, displayed to four decimal places by the handler. It is not a separate estimate and it is not an ANN index size. It simply expresses the same 7,168 bytes per vector at a smaller operational unit. If the vector count changes but dimensions, precision, and metadata stay fixed, this density remains constant while the total GB changes linearly.
The default is a starting scenario, not a universal profile. It includes no graph links, inverted postings, replicas, snapshots, compaction reserve, or separate original-content store. It also assumes the 1 KB metadata average is representative. Before using 7.17 GB as a capacity commitment, check whether the actual embedding output is float32, whether the payload is co-located, whether the system stores a full-precision copy, and whether the deployment needs one or more additional physical copies.
Precision sensitivity is easy to see when the default count, dimensions, and 1 KB metadata average remain fixed. At float32, the total is 7.168 GB. At float16, the vector term becomes 1,536 x 2 = 3,072 bytes, so each record uses 4,096 bytes and one million records use 4.096 GB. At int8, the vector term is 1,536 bytes, each record uses 2,560 bytes, and one million records use 2.56 GB. Metadata stays at 1.024 GB in all three cases, so it does not shrink with precision.
Count sensitivity uses the same default record shape. Ten million vectors require 71.68 GB, one hundred million require 716.8 GB, and one billion require 7,168 GB, which is 7.168 decimal TB. These totals are raw flat baselines. They demonstrate why a modest per-vector difference becomes significant at scale: a change of 100 bytes per vector is about 100 GB across one billion vectors before indexes and copies are considered.
Dimension and metadata can trade places in the total. One million vectors with 768 dimensions, float16 precision, and 1 KB of metadata use 768 x 2 + 1,024 = 2,560 bytes per vector, or 2.56 GB. One million vectors with 384 dimensions, int8 precision, and 4 KB of metadata use 384 + 4,096 = 4,480 bytes per vector, or 4.48 GB. In the second scenario, metadata is much larger than the vector values, so reducing vector precision further would have limited effect unless the payload is also redesigned.
Use one-variable comparisons to explain a capacity change. Hold count constant while changing dimensions to isolate model output shape. Hold dimensions constant while changing bytesPer to isolate precision. Hold both constant while changing metaKb to isolate schema and filter payload. Finally, multiply the logical baseline for replicas or add measured index and operational reserves outside the calculator. A scenario table with those columns makes it clear which assumption caused each increase.
This calculator reports decimal GB. One decimal GB is 1,000,000,000 bytes. A binary GiB is 1,073,741,824 bytes, which is 2^30. The two units describe the same byte total with different divisors. A value of 7.168 decimal GB is 7,168,000,000 bytes, which is about 6.68 GiB. Seeing a smaller number in GiB does not mean that bytes disappeared; it means the unit contains more bytes.
To convert a calculator result from decimal GB to GiB, multiply the displayed GB value by 1,000,000,000 and divide by 1,073,741,824. To convert GiB to decimal GB, multiply GiB by 1.073741824. Keep extra digits during this conversion when comparing close capacities. A display rounded to two decimal places can introduce a small additional difference, so use the underlying byte estimate or an unrounded GB value for a careful reconciliation.
The metadata conversion is a separate issue. The formula uses 1,024 bytes for each entered KB because that is the explicit contract of the record. The final division still uses 1,000,000,000 bytes per GB. Therefore the calculation is not using one universal base for every unit; it is following a defined conversion for the metadata field and a defined decimal convention for the output. Reproducing the exact formula matters more than applying a preferred naming convention to KB.
Hardware and operating-system interfaces do not always label their unit convention consistently. When a capacity panel shows a number that does not match the calculator, first compare bytes, then compare GB with GiB, then check whether the panel reports nominal capacity, free capacity, or usable capacity after reservations. Do not correct the calculator by changing its divisor without also changing the stated contract. Instead, convert both readings to bytes or to one clearly named unit.
The formula estimates a flat raw working set: vector values plus a flat per-vector metadata average. It does not calculate an approximate-nearest-neighbor index. An ANN structure commonly adds navigation links, record identifiers, graph or partition data, centroids, postings, codebooks, search parameters, or alignment space. Some designs retain the original vector values beside a search representation, while others build one or more derived structures. Those bytes are in addition to the raw terms unless a particular architecture explicitly replaces one stored representation.
Index overhead is not a single universal percentage. A graph-based structure can vary with neighbor degree, construction settings, and identifier width. A partitioned or inverted structure can vary with the number of partitions, list assignments, residual representation, and stored auxiliary data. Deletions may leave tombstones until maintenance runs. A query engine may also keep a hot index, a memory map, or temporary build buffers. The vector count and dimensions influence these components, but the calculator has no fields for their settings and therefore does not guess them.
The term Index working set in the result names the baseline used for planning a searchable collection; it should not be read as a complete ANN index size. Treat the number as the bytes that must exist before the chosen search structure is accounted for. After selecting an index design, measure a representative build or use documented per-record overhead from that implementation. Add the measured derived structure, not an arbitrary percentage copied from an unrelated workload.
Build and serving phases can have different peaks. A finished index may fit in a target memory budget while construction needs both the raw vectors and temporary builder state. A rebuild may also hold the old and new structures at once. Estimate the steady-state raw baseline with this page, then create separate peak scenarios for construction, reload, compaction, and migration. The calculator is a useful common input to each scenario, but it does not choose the ANN algorithm or its operating parameters.
Metadata is often more than a display label. A filtered search may need tenant identity, authorization scope, language, document state, date ranges, category values, or deletion markers. Each field may have a serialized value on the row and a separate lookup structure for filtering. The calculator's metaKb term can represent the serialized per-vector payload, but it does not automatically represent the indexes created over those fields. A payload that looks small in a JSON view can occupy more bytes after field names, type tags, offsets, allocator units, and internal storage structures are included.
Use an average that matches the physical representation rather than the logical schema alone. If every record has a fixed identifier and two short flags, measure the stored row or estimate those fields with the actual encoding. If some records carry long titles, access lists, or arrays, calculate a weighted average from representative groups. For a first pass, divide observed payload bytes by the number of vectors. For a conservative plan, also inspect the high end because a mean can conceal records that dominate memory during filtering or retrieval.
Filter indexes can duplicate information. A service may keep the original metadata, a compact dictionary for repeated values, postings for categorical filters, and range structures for timestamps or numbers. The raw payload and each derived structure may have different scaling behavior. If a filter is implemented outside the vector store, its storage belongs in that subsystem's estimate. If it is co-located, add its measured footprint to the raw baseline when planning total disk or memory.
Metadata design can change the storage curve without changing the embedding model. Normalizing repeated values may reduce payload bytes, while copying full text into every chunk may increase them sharply. Storing only stable identifiers can lower vector-service storage but may add lookup latency and external availability requirements. The calculator makes this tradeoff visible through metaKb, but it does not recommend a schema. Test filtering correctness, authorization behavior, update cost, and retrieval latency alongside the byte estimate.
The Precision selector provides three direct component-size scenarios, but it is not a complete compression model. float32 and float16 describe floating-point component widths, while int8 describes a one-byte component representation. A quantized vector may also need a scale, offset, codebook reference, or block header. A compressed representation may store components in blocks with padding or use shared parameters. Those additions can be small per block and large in aggregate, especially when vectors are short or auxiliary values are repeated per record.
Do not interpret int8 as a universal promise that every one-byte search representation has exactly one byte per dimension and no other bytes. In this calculator, int8 means one byte for the component term. If the actual encoding stores one scale per vector, one scale per block, or several codebook values, add those bytes to the average metadata or to a separate measured representation term in the larger plan. Keep the distinction visible so that a precision comparison does not look more exact than it is.
Compression can reduce raw vector bytes, but it can also change search quality and compute cost. Lower storage may require decompression during search, a different distance approximation, or a reranking stage with a full-precision copy. Evaluate recall, ranking stability, latency, CPU use, and rebuild time on representative data. A byte saving that forces a second copy for reranking may reduce the net saving. The calculator cannot infer that system-level tradeoff from bytesPer alone.
A sound compression estimate uses the encoded artifact whenever possible. Measure total encoded bytes for a representative batch, subtract no bytes for assumptions that were not measured, and divide by the number of vectors to obtain an average. If the result includes index structures, separate those from the vector representation before using it as a replacement for the calculator's raw term. This preserves an apples-to-apples comparison between raw values, compressed values, and ANN overhead.
The calculator describes one logical flat copy. It makes no replication assumption. If a deployment keeps three complete physical copies and every copy contains the same raw vectors and metadata, the raw replicated baseline is three times the one-copy result. For the default 7.168 GB scenario, that simple payload multiplication is 21.504 GB before ANN structures, storage-system overhead, snapshots, or temporary space. Real replicas may differ during repair or compaction, so a production plan should treat the multiplication as a baseline rather than a complete failure-domain budget.
Sharding distributes records across partitions; it does not make the logical collection smaller. With evenly distributed shards and no local overhead, dividing the raw baseline by the number of shards gives a rough per-shard payload. Actual distributions can be uneven because tenants, documents, time ranges, or embedding workloads are not perfectly balanced. Each shard may also have its own index metadata, service process, reserved memory, and replica set. Estimate total logical bytes first, then model placement, skew, and per-shard fixed costs.
Growth planning should use the ingestion and retention policy, not only today's count. If a collection grows from one million to ten million vectors, the raw terms grow by a factor of ten. If old vectors are retained during a re-embedding migration, the peak can approach the sum of both generations. Backups, snapshots, write-ahead logs, compaction workspaces, and delayed deletion can raise required disk above the live collection. Add those lifecycle stages as explicit scenarios instead of hiding them in metaKb.
A practical capacity sheet keeps separate rows for logical raw bytes, replicas, ANN structures, filter indexes, operating reserve, growth reserve, and migration peak. The calculator supplies the first row and can be rerun for each future vector count. For a forecast, choose a review interval and recalculate with the expected count at that date. When measured index or payload data becomes available, replace the provisional terms with measured averages and retain the original calculator inputs for traceability.
The reported number is a byte estimate for a flat collection, not a promise that the same number of bytes will be resident in RAM. A disk-backed service may keep only hot vectors or index pages in memory, while a memory-oriented service may need most or all vectors resident for predictable search latency. Memory mapping and operating-system page cache can make a disk file appear in process or system memory without changing the underlying file size. The relevant capacity question depends on whether the target is persistent disk, available RAM, device memory, or a combination.
Disk planning usually includes more than the live raw collection. A service may retain immutable segments, transaction logs, snapshots, backup staging, deleted records awaiting compaction, and a temporary output during index rebuild. A memory plan may need index pages, filter structures, query buffers, batch allocations, and multiple concurrent searches. None of these are represented by the flat formula. The result is best treated as the minimum data-bearing baseline that every complete architecture must account for somewhere.
The same bytes can have different operational effects depending on access pattern. Sequential bulk loading may tolerate storage that is too slow for random search. A collection that fits on disk may exceed available memory when the chosen ANN structure is loaded. A service that keeps vectors on disk may incur latency when queries touch cold pages. Conversely, a generously sized memory cache does not eliminate the need for durable disk, replicas, or recovery copies. Use separate memory and disk rows in the design, even when both start from this same raw estimate.
When validating a deployment, measure both steady state and peak. Observe resident memory after loading, memory during concurrent queries, disk usage after compaction, and temporary usage during backup or rebuild. Compare those measurements with the calculator's byte baseline after converting all values to the same unit. A difference is not automatically an arithmetic error; it may be the expected contribution of the index, payload encoding, cache, or lifecycle reserve.
The handler validates vector count and dimensions as finite whole numbers within their catalog ranges. Vector count must be from 1 through 1,000,000,000,000, and dimensions must be from 1 through 1,000,000. Precision must be one of the exact values 4, 2, or 1 from the selector. Metadata per vector must be finite and between 0 and 1,000,000 KB, with fractional values allowed. These rules prevent a fractional record count, unsupported precision, negative payload, or unbounded scenario from being treated as a normal estimate.
The calculation should be done with full numeric precision before the result is formatted. In the default scenario, 7.168 GB is displayed as 7.17 GB because the result precision is two decimal places. Do not multiply 7.17 by a replica count when a more exact 7.168 value is available, and do not round per-vector bytes before multiplying by a large count. At scale, a small per-vector rounding error can become a large absolute difference. Keep raw bytes or sufficient decimal places in planning records.
A manual validation can check the calculation in stages. Confirm that the selector value maps to the intended bytes per component. Compute vector bytes per record, metadata bytes per record, and their sum. Multiply by the integer vector count. Divide by 1,000,000,000 for decimal GB and compare the displayed value only after rounding. Then compute bytes per 1,000 vectors and compare the secondary result. This staged method makes it easy to locate a mismatch in precision, metadata conversion, count, or output units.
Boundary testing is valuable even for a simple formula. Test one vector with one dimension and zero metadata, the largest permitted count with ordinary dimensions, fractional metadata, every precision option, and invalid fractional counts. Test a large metadata value separately because it can dominate the vector term. The handler rejects a non-finite final result as an overflow safeguard. If a planning spreadsheet produces a different result at extreme values, compare exact bytes and numeric representation rather than assuming that the rounded GB display is authoritative.
A metadata average is often the least obvious input because application schemas are described in fields while storage systems allocate bytes. Start with a representative sample of records. Include the identifier, filterable attributes, tenant or authorization data, timestamps, version markers, and any payload that is physically co-located with the vector. Measure serialized size or stored segment contribution consistently across the sample. Divide the measured metadata bytes by the number of vectors to obtain an average expressed using the calculator's 1,024-byte KB rule.
Separate fixed and variable components when the distribution is uneven. A required identifier may contribute to every vector, while a large access list may appear only on a minority. Calculate the weighted mean across those groups rather than using the smallest common record as the estimate. Also inspect a high percentile or worst-case group for query-memory planning. The calculator accepts one flat average, so the burden is on the surrounding plan to preserve tail information when a mean would understate operational risk.
Do not place unrelated architecture costs into metadata merely to make the final number look complete. A replica, ANN graph, backup, or cache is not per-vector payload just because it grows with vector count. Putting it into metaKb can be a temporary rough estimate, but it obscures which component changed and makes later measurement difficult. Keep the calculator's metadata input for actual flat per-vector payload and list derived structures as separate lines in the capacity model.
Metadata also changes over time. New filter fields, longer labels, permission changes, and schema migrations can raise the average without changing vector count or dimension. Recalculate the input when the payload schema changes. If records are updated in place through a segment-based system, the live bytes may remain higher until compaction. A current sample and a migration peak sample can therefore justify two metaKb scenarios rather than one permanent value.
First define what one vector means in the application. Decide whether the count is documents, chunks, images, events, or another unit, and record whether one source item can create multiple vectors. Confirm the actual output dimension from the embedding pipeline and confirm the physical component representation. A name such as high precision or compressed is not enough; the estimate needs a byte choice or a measured average that can be mapped to the selector and documented alongside it.
Next measure or bound the co-located metadata. State which identifiers, filter fields, permissions, timestamps, and payload portions are included. Enter a defensible average and retain the sample or derivation outside the calculator. Run the default or current-count scenario, then run one-variable comparisons for precision, dimensions, vector count, and metadata. Record the unrounded result, the displayed GB, and the per-1,000-vector density so another person can reproduce the baseline.
After the raw baseline is established, add architecture rows: ANN index, filter indexes, replicas, shards, storage-system reserve, backups, growth, and migration peak. For each row, label whether it is measured, documented, or provisional. Do not turn a provisional index percentage into a fact merely because it produces a convenient total. Re-run the calculator whenever count, dimension, precision, or payload average changes, and update the separate rows when the chosen search implementation is tested.
Finally validate the plan on a representative subset. Build the intended vector and metadata representation, measure bytes on disk, observe memory after loading, and test the query workload at the expected concurrency. Compare measured raw bytes with the calculator before comparing total system use. This order distinguishes a formula mismatch from an index or operational effect. It also creates evidence for a future estimate instead of relying on a single optimistic default.
This estimator does not choose an embedding model, verify a model's dimension, or judge whether an embedding is useful for a search task. It does not select a distance metric, normalize vectors, evaluate recall, determine a similarity threshold, or predict relevance. It assumes that you already know the vector count and stored dimensions for the scenario. If those inputs are uncertain, run several explicit scenarios or measure the output of the real embedding pipeline rather than treating the defaults as facts about an unspecified model.
It does not calculate a complete ANN index size, filter-index size, graph or posting configuration, query cache, process overhead, or build workspace. It does not decide whether vectors and payloads belong in memory, on local disk, on remote storage, or across a tiered design. It does not determine how replicas are placed, how shards are balanced, how failover works, or how much free capacity is required for repair. Those decisions need architecture-specific measurements and operational requirements.
It also does not decide compression quality, quantization error, latency, throughput, concurrency capacity, update rate, recovery time, or cost. A smaller raw byte result may require more compute, a full-precision reranking copy, or a more complex migration. A larger uncompressed result may simplify quality validation. The calculator exposes the storage arithmetic for the selected bytes per component, but it cannot trade storage against search quality or service objectives.
The estimator is therefore a baseline and comparison tool, not a deployment approval. Its strongest claim is conditional: for the entered number of vectors, dimensions, precision bytes, and flat metadata average, the stated formula produces this many decimal GB. Use that conditional result to structure a broader capacity plan, keep raw and derived terms separate, and replace assumptions with measurements as soon as the actual representation and workload are available.
Estimate storage for an embedding index from vector count, dimensions, and precision.
Bytes = vectors × (dims × bytesPer + metaKB × 1024). Raw vector bytes plus per-item metadata give the working set before index overhead. ANN indexes (HNSW, IVF) add their own overhead on top.
Enter Vector count, Dimensions, Precision, Metadata per vector, then choose Calculate.
Flat storage; no compression, quantization indexes, or replication. Decimal GB (10^9 bytes) reported. Metadata is a flat per-vector average.
This calculator is part of the WorldCalculate library. Its formula, example, assumptions, input bounds, and output formatting follow the official methodology.
These WorldCalculate collections connect this tool with related questions while keeping each calculation separate and transparent.