
Goal
Calculate Pearson’s r, r², means, and supporting sums from paired X and Y observations entered as comma-separated values.
Worldwide context
Saved once here, used across the site.
Currency changes display only. Country selection guides tax input; no tax rate is guessed.
Calculate Pearson’s r, r², means, and supporting sums from paired X and Y observations entered as comma-separated values.
r = Σ[(xᵢ − x̄)(yᵢ − ȳ)] ÷ √(Σ(xᵢ − x̄)² × Σ(yᵢ − ȳ)²); r² is the squared coefficient.A clearer path to an answer
This page keeps the calculation transparent: define the goal, enter the matching values, inspect the method, and decide what the result means in your situation.
Calculate Pearson’s r, r², means, and supporting sums from paired X and Y observations entered as comma-separated values.
X values · Y values
r = Σ[(xᵢ − x̄)(yᵢ − ȳ)] ÷ √(Σ(xᵢ − x̄)² × Σ(yᵢ − ȳ)²); r² is the squared coefficient.
Calculate, review the assumptions below, then compare a related tool when the decision needs more context.
Calculate Pearson’s r, r², means, and supporting sums from paired X and Y observations entered as comma-separated values.
Open the Pearson Correlation Calculator pageMore statistics tools
Download PDFDownload Word (.doc)
Enter your values above and choose Calculate to see the result here.
Calculation map
r = Σ[(xᵢ − x̄)(yᵢ − ȳ)] ÷ √(Σ(xᵢ − x̄)² × Σ(yᵢ − ȳ)²); r² is the squared coefficient.
Bounded, transparent calculation
Your recent runs stay in this browser session only.
Formula: r = Σ[(xᵢ − x̄)(yᵢ − ȳ)] ÷ √(Σ(xᵢ − x̄)² × Σ(yᵢ − ȳ)²); r² is the squared coefficient.
Pearson’s r summarizes the direction and strength of a linear association in paired numeric observations. The result is accompanied by means and r² so the calculation remains inspectable.
Worked example: The paired data have r ≈ 0.870 and r² ≈ 0.758.
The displayed limits are checked before the handler runs. Model-specific domain checks may also reject impossible or non-finite inputs.
Methodology: This calculator follows the WorldCalculate input, formula, precision, and boundary policy. Read the official methodology.
Calculator usage statistics
This section counts anonymous successful Calculate submissions, not unique visitors. Counts and top tools appear only when trusted aggregate data is available; country analysis is shown only under the same condition and reporting threshold.
Answer-first guide
Calculate Pearson’s r, r², means, and supporting sums from paired X and Y observations entered as comma-separated values. Start with one clearly defined goal, enter values in the units shown, and keep the result attached to the assumptions below.
This tool is useful when your question includes Pearson correlation calculator, Pearson r calculator, correlation coefficient. It returns the outputs declared in the calculator contract rather than a live quote, approval, diagnosis, or professional sign-off.
X values · Y values. Keep the same time period, unit system, and currency wherever the form requires comparable values.
Run the worked example first, compare its output with the page's example, then change one input at a time. This makes an unexpected result easier to trace to a unit, boundary, or assumption.
Need a wider view? Browse Statistics Calculators or compare the related tools below. The WorldCalculate methodology explains how formulas, examples, limits, and revisions are reviewed.
r = Σ[(xᵢ − x̄)(yᵢ − ȳ)] ÷ √(Σ(xᵢ − x̄)² × Σ(yᵢ − ȳ)²); r² is the squared coefficient.
Pearson’s r summarizes the direction and strength of a linear association in paired numeric observations. The result is accompanied by means and r² so the calculation remains inspectable.
The paired data have r ≈ 0.870 and r² ≈ 0.758.
Context and background
Statistics tools describe data or evaluate a stated probability model. They do not turn an observed summary into causation, certainty, or a forecast without additional evidence.
Data analysis developed from summaries of observations into probability, estimation, and decision measures. The essential habit remains the same: define the population, sample, variable, and convention before calculating.
Research and review
Researched by Hassan ALRowaie, Founder and editorial researcher at WorldCalculate.
This guide follows the live calculator's declared inputs, formula, worked example, assumptions, validation boundaries, and source-backed methodology. The review date describes editorial review of the calculator explanation; it is not a promise that external facts or rates remain current.
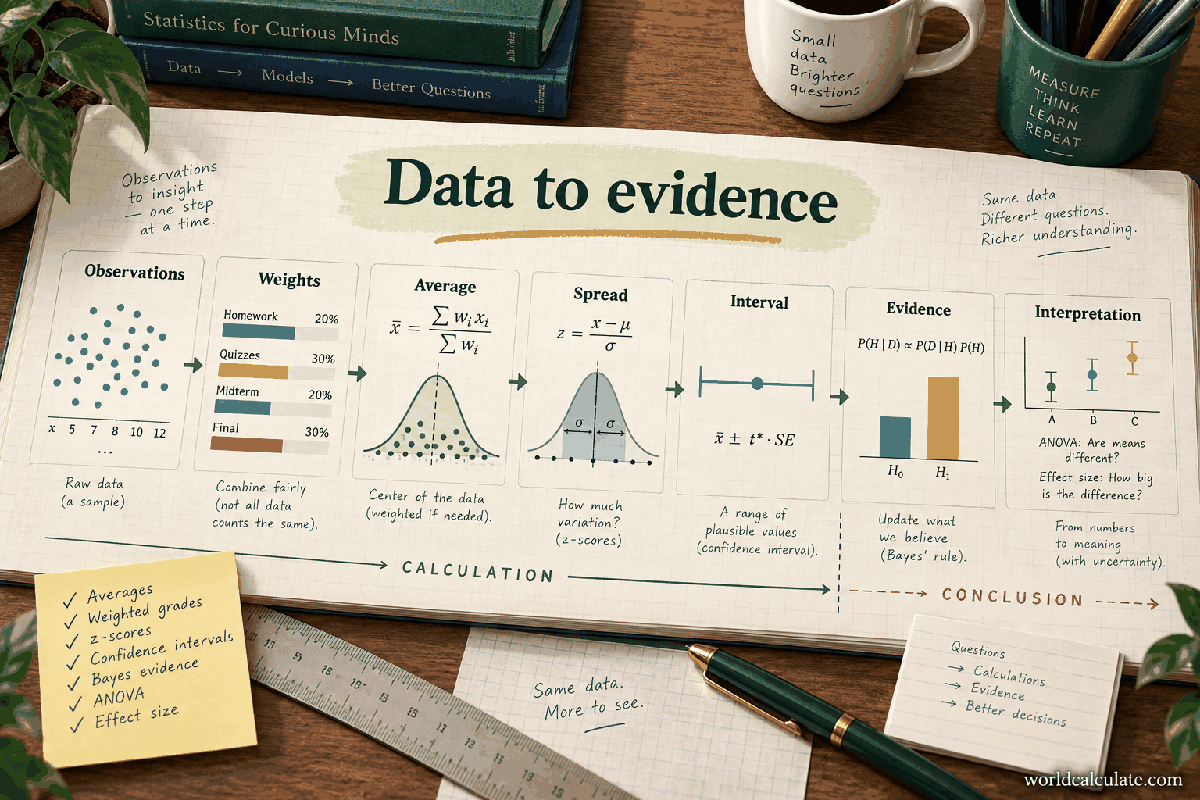
Pearson’s correlation coefficient is useful when the question is about a linear relationship between two measured variables. This calculator accepts paired lists and exposes the means and squared result so the statistic can be checked rather than treated as a magic label.
Pearson’s r is a unit-free summary of linear association. It ranges from −1 to +1 when computed from non-constant paired data, with the sign indicating direction.
Subtract each variable’s mean, multiply the paired deviations, and divide their sum by the square root of the two centered sums of squares. The denominator standardizes the cross-product.
The first X value belongs with the first Y value, the second with the second, and so on. Commas, spaces, and semicolons are accepted, but both lists must have the same length.
For X = 1, 2, 3, 4, 5 and Y = 2, 4, 5, 4, 7, the calculator centers both lists and returns a positive correlation of about 0.870, with r² about 0.758.
Squaring r removes its sign and gives the proportion of variation in a simple linear description associated with the fitted relationship under the chosen data and interpretation. It is not a universal prediction accuracy measure.
A high correlation can arise from coincidence, a common third variable, selection effects, or a shared time trend. The statistic alone cannot identify a mechanism or justify an intervention.
Inspect a scatter plot, look for influential outliers, confirm the measurement scale, and explain how the observations were sampled. A number with eight displayed decimals is not automatically a precise scientific conclusion.
Pearson’s r is useful when the practical question is whether two numeric variables move together in an approximately linear way. It is not a universal association detector, a causality test, or a substitute for looking at the observations. Before entering values, name X, name Y, identify the unit of each, and explain why the pairs belong together.
That small preparation changes how the output is read. A positive r means that larger X values tend to accompany larger Y values in this sample’s linear pattern; a negative r means the direction tends to reverse. Neither sign explains why the pattern exists. The calculator summarizes a defined dataset, not an unnamed relationship.
The first X value is paired with the first Y value, the second with the second, and so on. If a spreadsheet is sorted by X without moving the Y column with it, the pairs change and the statistic may describe a different dataset. The calculator cannot detect every semantic pairing error because the numbers can remain finite and equal in count.
Keep a row identifier or observation label during data preparation. For a short list, write the pairs as a two-column table before copying them into the fields. If a measurement is missing, do not delete only one value; resolve the row according to the study’s missing-data rule, then document the resulting sample.
For the example X = 1, 2, 3, 4, 5 and Y = 2, 4, 5, 4, 7, the means are x̄ = 3 and ȳ = 4.4. The centered cross-products sum to 10, the X squared-deviation sum is 10, and the Y squared-deviation sum is 13.2. Therefore r = 10 ÷ √(10 × 13.2) ≈ 0.870.
Writing these intermediate sums beside the output provides an independent audit. It also explains why a unit change, such as metres to centimetres, does not change r: the centered scale factor appears in both the numerator and the matching denominator. The means and sums remain useful evidence even when the final coefficient is rounded for a report.
The sign describes the direction of the linear association in the entered sample. Values near zero show little linear alignment, while values closer to either endpoint show stronger linear alignment under the data and assumptions. There is no single universal cutoff that makes a coefficient weak, moderate, or strong in every field.
Interpret size with the design, measurement quality, sample size, and scientific context. A small coefficient may matter in a noisy physical process, while a large coefficient in an observational dataset may still be confounded. Use a contextual explanation instead of a copied adjective that hides the decision that the number is meant to inform.
Mathematically, Pearson’s r is unchanged if X and Y are exchanged. The research story may not be interchangeable, however. Age and reaction time can have a symmetric coefficient while the theory and measurement error differ depending on which variable is considered an outcome.
Name the variables before reporting the statistic and preserve their units in the table. If the next step is a regression or prediction model, distinguish the descriptive symmetric correlation from the directional modeling choice. The calculator gives the coefficient; it does not select the response variable or establish a mechanism.
The coefficient r retains direction and uses the standardized linear cross-product. Squaring it gives r², which removes the sign and describes a proportion-like fit summary in the simple linear setting. The two values should not be presented as interchangeable: r can be negative while r² is positive.
An r² of 0.758 in the worked example does not mean that 75.8 percent of every future observation is guaranteed or that the relationship is causal. It summarizes the entered sample under a particular model description. State the sample, model, and evaluation context whenever r² is used in a decision or report.
Two datasets can share the same correlation while having different shapes, clusters, outliers, or leverage points. A scatter plot is therefore a companion diagnostic, not decoration. Look for a curve, separated groups, a funnel shape, a single extreme point, or a time ordering that the coefficient compresses.
If the plot shows a nonlinear pattern, Pearson’s r may be modest even though the variables are strongly related. If a single point drives the slope, the coefficient may change materially when that point is checked. The calculator reports the arithmetic for the values entered; visual diagnosis decides whether that arithmetic is an adequate summary.
Pearson’s r is designed for paired numeric quantities where differences and products of deviations have a meaningful interpretation. Coding categories as 1, 2, and 3 can create an artificial numeric spacing if the labels are not genuinely ordered with equal intervals. A finite list is not automatically a valid measurement scale.
Check whether the variables are continuous, counts, scores, proportions, or coded groups. A specialist may choose another association measure when the scale, distribution, or question requires it. The result should be named with the method used, not described broadly as ‘correlation’ without saying Pearson’s r.
This calculator describes the entered observations. Whether they are a complete population, a sample, a convenience group, or a repeated measurement series changes the inference that can be made from the coefficient. The arithmetic alone does not add a confidence interval, p-value, or generalization to an unobserved population.
When inference matters, report how the observations were selected and use an appropriate statistical procedure for uncertainty. Do not attach a p-value copied from a different sample or assume that a large-looking r is statistically meaningful without considering sample size and design. Keep descriptive output and inferential claims separate.
An outlier can change the means, centered products, denominator, and final r at once. Missing values can change which pairs remain. A time series can show a high correlation simply because both variables trend over time. These are data questions, not numerical formatting problems.
Before reporting, record the cleaning rule, identify any excluded rows, and inspect the series in its original order. If a result changes after a justified sensitivity check, show that range and explain why. Never remove a point solely because it weakens a desired conclusion without documenting a pre-specified reason.
For a small dataset, compute the baseline r, then repeat the analysis after a documented alternative such as a measurement correction or a clearly justified exclusion. Compare r, r², the scatter plot, and the number of paired observations. This does not make the choice objective automatically, but it shows whether the conclusion depends on one assumption.
Another useful comparison is to split data by a meaningful group or period when the design supports it. A pooled coefficient can differ from within-group coefficients. Do not create groups merely to obtain a preferred sign. The grouping question must come from the subject matter and be recorded before interpreting the new numbers.
A concise report can state the variable names and units, number of paired observations, Pearson’s r to a sensible number of decimals, r² when relevant, the data source, and the scatter-plot or diagnostic checks performed. Include the direction in plain language and avoid claiming causation.
For the worked list, a reproducible sentence would say that five paired observations produced Pearson’s r ≈ 0.870 and r² ≈ 0.758 for the named X and Y values. The exact values matter less than keeping the dataset, method, and rounding visible. Another reader should be able to reproduce the result from the record.
The tool cannot decide whether the variables are measured correctly, whether pairs are independent, whether a relationship is causal, whether a sample represents a population, or whether Pearson’s method is appropriate for the research question. It also does not identify influential observations or construct uncertainty intervals.
Those limits are not defects in the arithmetic; they define its safe use. Use the output as one transparent descriptive step, then add a plot, design review, and appropriate inferential method when the decision requires more than a coefficient. A precise number cannot repair an unclear study question.
Define X and Y, preserve row pairing, verify units and numeric scale, inspect the data visually, and enter the lists without silently changing their order. Check the means and output range, then compare the result with a hand calculation or an independent statistical tool for important work.
Save the exact lists or a traceable data reference, cleaning decisions, calculator date, and displayed result. If the dataset changes, treat the new coefficient as a new analysis rather than overwriting the old value. This makes corrections possible and prevents a small exploratory worksheet from becoming an untraceable published claim.
A short table can show each pair, the centered X deviation, the centered Y deviation, the cross-product, and the two squared deviations. It is more informative than copying a coefficient into a report because it reveals how every row contributes to the numerator and denominator. The table also makes a swapped pair or unusual observation easier to spot.
For a classroom exercise, calculate the means first, fill the deviation columns, sum them, and then use the formula. For a research analysis, retain the table or a reproducible data reference rather than hand-editing the final number. The calculator’s supporting sums are useful precisely because they preserve this audit trail without requiring a visitor to expand every row manually.
Changing X from metres to centimetres or Y from kilograms to grams applies a constant scale to the relevant deviations, so Pearson’s r is unchanged when the conversion is applied consistently. That does not mean the measurement process is irrelevant. Rounding, calibration error, range restriction, and inconsistent definitions can alter the observed pairing and therefore the coefficient.
Record the original units and any conversions before entering the values. If one variable is measured with much more noise than another, interpret the association as an observed relationship under that measurement system. Unit invariance is a mathematical property, not a guarantee that two instruments measured the same construct reliably.
Pearson’s r is symmetric and unit-free. A regression slope is directional and carries units of Y per unit of X. In a simple linear model, the sign of the slope follows the sign of r, but the slope also depends on the standard deviations and the chosen variable roles. A correlation coefficient cannot be substituted for a regression equation.
If the next question is prediction, use a fitted model with residual diagnostics and uncertainty rather than treating r as a conversion factor. If the question is association, report r with the data context. Linking the two tools can be helpful, but the article should tell the reader which question each result answers.
If the entered observations cover only a narrow slice of the possible X or Y range, r may be smaller than the relationship across the full population. Conversely, selecting a group because both variables are already high can create a different pattern from the source population. The calculator sees only the supplied range and cannot correct selection effects.
Describe how the observations were obtained and what range is represented. Compare a restricted dataset with the broader design only when the sampling supports that comparison. Never inflate the coefficient by adding hypothetical endpoints or by combining incompatible groups merely to widen the range.
A pooled dataset can show a strong association because two groups have different means even when the within-group relationships are weak or reversed. A scatter plot with group labels can reveal this structure. The pooled r is still the correct arithmetic for the pooled pairs, but it may not answer a within-group question.
If group membership is scientifically meaningful, calculate and report the appropriate subgroup summaries with their sample sizes and design caveats. Do not split groups only after seeing a preferred result. The calculator can be used repeatedly for defined subsets, but the reason for each subset must come from the subject matter or study plan.
A coefficient from a finite sample is an estimate of an association in that sample context. This worksheet does not calculate a confidence interval, a hypothesis test, or a power analysis. Those quantities depend on assumptions about sampling, independence, distribution, and the inferential question.
When uncertainty matters, use a statistical method suited to the design and report the interval or test with its assumptions. Do not make an inference stronger by displaying more decimal places. The calculator can remain the reproducible descriptive baseline from which the more complete analysis begins.
For the example with r ≈ 0.870, a careful interpretation is that the five entered pairs show a strong positive linear association under this sample. It is not that changing X will necessarily cause Y to change, and it is not that 87 percent of a person, machine, or future measurement is explained.
Ask what alternative explanations remain: a third variable, common time trend, selection process, measurement artifact, or chance. A useful article answers that question next instead of celebrating the coefficient. The result becomes a starting point for investigation, not a shortcut around research design.
If the reader needs a visual check, the next action is a scatter plot. If the reader needs a directional estimate, a linear regression tool may be appropriate. If the variables are ranks or categories, another association measure may fit better. If the data are repeated over time, a time-series or within-subject analysis may be needed.
Internal links should explain that next question in their anchor text. A link to a regression calculator is useful after the article explains response and predictor roles; a link to a generic statistics hub is useful for the broader method context. Avoid linking every tool merely because it shares the word correlation.
Short lists entered into a browser tool may still represent people, experiments, customers, or confidential measurements. Do not publish identifiable observations in a screenshot or copy them into a public article without permission. The calculator is suitable for a small exploratory input, but sensitive data should follow the organization’s approved analysis environment.
For a public example, use synthetic or openly licensed values and label them as examples. For a private analysis, keep the raw data under the appropriate access controls and store only the derived summary that the audience is allowed to see. Reproducibility does not require exposing confidential rows.
Before using r, confirm that each X value is paired with the intended Y value, both lists have the same length, neither variable is constant, the sample size is adequate for the stated purpose, and a scatter plot has been considered. Name the coefficient as Pearson’s r and preserve the units and source context.
Then report r and, if useful, r² with sensible rounding and an honest limitation statement. If the pattern is curved, clustered, driven by an outlier, or tied to time, investigate that structure before drawing a conclusion. The next step may be a different model or a better data collection plan, not a stronger adjective for the same number.
Before using r, confirm that each X value is paired with the intended Y value, both lists have the same length, neither variable is constant, the sample size is adequate for the stated purpose, and a scatter plot has been considered. Name the coefficient as Pearson’s r and preserve the units and source context.
Then report r and, if useful, r² with sensible rounding and an honest limitation statement. If the pattern is curved, clustered, driven by an outlier, or tied to time, investigate that structure before drawing a conclusion. The next step may be a different model or a better data collection plan, not a stronger adjective for the same number.
What if X never changes? r is undefined because the denominator is zero. Can r be greater than 1? Not for valid non-constant data; such an output would signal an implementation or data problem. Does r measure any nonlinear relationship? No; a curved relationship can have a modest r even when the variables are strongly related.
Calculate Pearson’s r, r², means, and supporting sums from paired X and Y observations entered as comma-separated values.
r = Σ[(xᵢ − x̄)(yᵢ − ȳ)] ÷ √(Σ(xᵢ − x̄)² × Σ(yᵢ − ȳ)²); r² is the squared coefficient. Pearson’s r summarizes the direction and strength of a linear association in paired numeric observations. The result is accompanied by means and r² so the calculation remains inspectable.
Enter X values, Y values, then choose Calculate.
X and Y contain the same number of finite numeric observations. At least three paired observations are entered. Neither variable is constant; otherwise Pearson’s r is undefined. The observations are paired in order, so xᵢ and yᵢ describe the same row or case. The coefficient describes linear association and does not prove causation. Outliers, missingness, measurement error, and sampling design are not automatically diagnosed. Interpretation should include the study context, a scatter plot, and appropriate uncertainty analysis.
This calculator is part of the WorldCalculate library. Its formula, example, assumptions, input bounds, and output formatting follow the official methodology.
These WorldCalculate collections connect this tool with related questions while keeping each calculation separate and transparent.